
Source: ByteDance Seed's official SeedRealtime launch article.
SeedRealtime is ByteDance's attempt to move AI conversation beyond “ask, wait, answer.” The model is designed to keep watching and listening while deciding whether to speak, pause, or stay quiet.
That is a meaningful product change. It is not yet proof that always-on multimodal assistants work reliably outside carefully chosen demos.
Quick Navigation
- What is SeedRealtime? The product, availability, and evidence boundary.
- What changed? Continuous audio-video interaction instead of clean turns.
- How does it work? One end-to-end model and model-controlled turn timing.
- Who should try it now? Doubao users with a concrete visual task.
- Why should developers wait? No public API, model card, or independent SeedRealtime evaluation yet.
- FAQ: Five direct answers about access, privacy, testing, and developer use.
What We Know So Far
ByteDance Seed announced SeedRealtime on August 5, 2026 in China and says it is fully rolled out in the Doubao app. IT Home independently reported the same release and access path: update Doubao, choose the call option, and enter a video call.
The architecture, performance statements, and examples still come from ByteDance. The launch page does not link a public API, model card, technical report, or reproducible SeedRealtime benchmark. We therefore treat the demos as evidence of what ByteDance showed, not independent proof of general reliability.
What is SeedRealtime?
SeedRealtime is ByteDance Seed's new full-duplex audio-video model, built to watch, listen, and speak over one continuous multimodal stream instead of waiting for a clean turn. ByteDance says the model joins audio, video, text, and timing in one end-to-end architecture and decides when to respond without handing turn detection to an external voice-activity detector. The company has rolled it out in the Doubao app, where users can enter a video call from the “Call” option. That availability is confirmed by ByteDance's launch post and independently reported by IT Home. The limit matters: public evidence is still dominated by vendor demos, no public developer API or technical report is linked from the launch, and an independent full-duplex benchmark paper does not test SeedRealtime. Treat it as a real product release worth trying in Doubao, not as proof that continuous multimodal assistants are solved.
What changed with SeedRealtime?
- Wait for a user to finish speaking: SeedRealtime's proposed change: Keep listening while deciding when to answer; Why users may notice: Fewer rigid start-stop turns, if timing works
- Analyze a submitted image or short clip: SeedRealtime's proposed change: Watch a changing video stream continuously; Why users may notice: The assistant can react to an event instead of one frozen frame
- Use separate speech recognition, visual understanding, and speech output stages: SeedRealtime's proposed change: Fuse audio, video, text, timing, and response generation in one model; Why users may notice: Less information may be lost between modules, according to ByteDance
- Use an external voice-activity detector to decide whose turn it is: SeedRealtime's proposed change: Let the model make turn decisions from multimodal context; Why users may notice: Interruptions and background speech can become part of the reasoning problem
This is a product-interface shift, not merely a new benchmark score. ByteDance's strongest demonstrations involve tasks that would be awkward with repeated screenshots: watching pages until a target section appears, correcting a coffee-making step, noticing a museum object, and following conversation in noisy or multi-person settings.
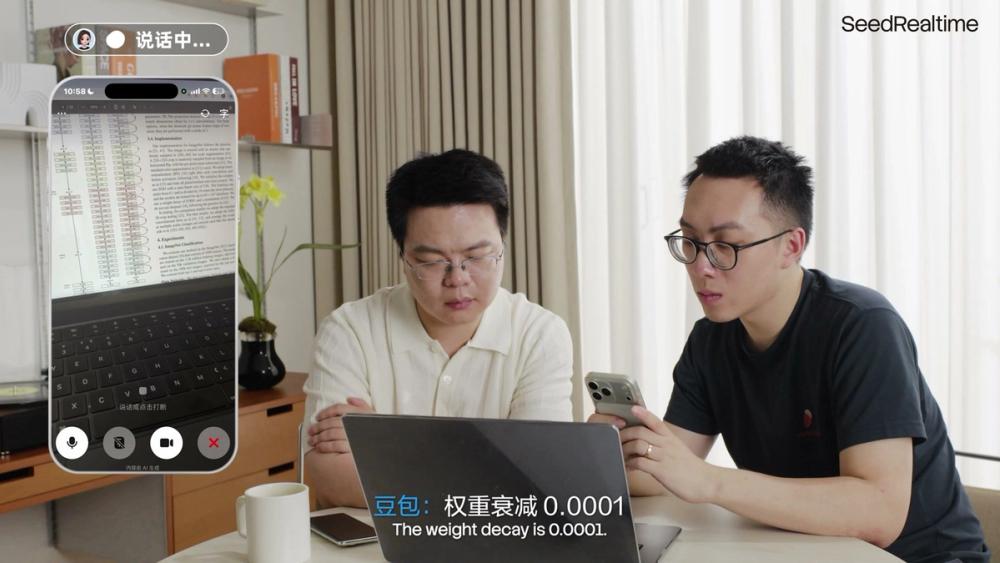
Source: ByteDance Seed's official ResNet-watching demo. This representative frame shows the vendor's model identifying and reading implementation details in its demo; it does not establish independent accuracy or reliability.
How does full-duplex audio-video AI work?
A normal voice assistant often behaves like a relay race. Speech recognition turns audio into text, a language or vision model decides what it means, and text-to-speech produces a reply. A voice-activity detector may decide that the user stopped talking and hand over the turn.
ByteDance says SeedRealtime instead processes continuous audio and video jointly and keeps perception, understanding, response timing, and expression inside one end-to-end model. In practical terms, the model must solve two problems at once: understand what is happening and decide whether now is the right moment to respond.
That timing decision is hard. An independent research benchmark, VideoFDB, was revised shortly before this launch and found that tested vision-speech agents often ignored the visual stream or reduced it to captions. VideoFDB did not test SeedRealtime, so it cannot confirm or refute ByteDance's claims. It does explain why continuous audiovisual grounding needs independent evaluation rather than a highlight reel.
The developer view
Developers should focus on the missing product surface. ByteDance has shipped a consumer experience in Doubao, but the launch page does not expose an API, latency budget, context policy, data-retention contract, pricing, or reproducible evaluation package.
If an API arrives, the first useful test is not an open-ended chat. Build a small event-detection task with objective checkpoints: watch a procedure, identify one target state, interrupt only when necessary, ignore controlled background speech, and log false alarms, missed events, response delay, and user corrections.
Until those measurements are possible, SeedRealtime is a design signal for builders—not a production dependency.
The product enthusiast view
If you already use Doubao and can access the video-call feature, try a bounded visual task. Ask it to watch for one page, object, or procedural mistake. Keep the task short, avoid sensitive material, and check whether it reacts at the correct moment rather than merely giving a plausible description.
For US users, the practical answer is different. The launch announces Doubao availability but does not announce a US rollout or an English-language developer service. Unless you already have supported access, waiting is more sensible than finding an unofficial wrapper that may misrepresent the model or its data practices.
Who should try SeedRealtime now—and who should wait?
Try it now if:
- You already have supported Doubao access. 2. You want to test one low-risk visual or conversational workflow. 3. You can judge success from an observable event, not from how natural the demo feels.
Wait if:
- You need an API, US availability, pricing, or a service-level commitment. 2. Your workflow contains private conversations, faces, documents, or regulated data. 3. You need independent reliability numbers across accents, languages, noise, multiple speakers, or long sessions. 4. You need the model to take actions through tools. ByteDance lists tool use and real-world task execution as future work, not a shipped capability.
My call: SeedRealtime is worth trying as a consumer interaction preview. Developers should study the interface idea and wait for an inspectable platform.
What remains unclear?
The largest gap is independent evaluation. ByteDance reports better conversational timing than a cascaded baseline, but the public launch does not provide enough methodological detail or an original evaluation artifact for us to reproduce or safely restate the numerical result.
The second gap is operational. ByteDance itself lists lower latency, more natural pacing, stronger proactive perception, better multi-person and noisy-scene handling, and tool-connected action as areas for further work. Those roadmap items are an unusually useful warning label: the hardest real-world cases remain active problems.
Privacy is also central. A system that continuously watches and listens creates different consent and retention questions than a chatbot that receives a typed prompt. The launch page does not answer those deployment questions for US teams, so organizations should not infer a compliance boundary from the consumer demo.
Quick Take
- What is actually new?: Evidence-backed answer: A consumer AI interaction that continuously combines audio, video, and response timing instead of waiting for separate turns.
- Who can use it now?: Evidence-backed answer: Doubao users with the latest app and access to the video-call flow, according to ByteDance and IT Home.
- What is the strongest evidence?: Evidence-backed answer: The live product rollout, official demos, and ByteDance's own description of the architecture and limits.
- What should users test?: Evidence-backed answer: One observable visual event, plus timing, interruptions, background speech, and corrections.
- What should developers wait for?: Evidence-backed answer: A public API, technical documentation, privacy terms, pricing, and independent SeedRealtime-specific evaluation.
SeedRealtime matters because it makes continuous multimodal conversation feel like a product decision rather than a lab concept. The next question is whether the experience survives ordinary rooms, ordinary networks, and ordinary mistakes.
FAQ
What is SeedRealtime?
SeedRealtime is ByteDance Seed's full-duplex audio-video model for continuous conversation. ByteDance says it jointly processes audio, video, text, and timing so the assistant can watch, listen, and speak without waiting for a clean one-question-one-answer turn.
Is SeedRealtime available now?
Yes, in ByteDance's Doubao app according to both the official launch and IT Home. Users are instructed to update the app, choose the call option, and enter a video call. The announcement does not establish general US availability.
Has SeedRealtime been independently tested?
Not in any SeedRealtime-specific public evaluation we found. IT Home independently confirms the release but repeats the vendor's technical claims. VideoFDB provides a useful independent benchmark for the broader full-duplex field, but it does not include SeedRealtime.
Can developers use a SeedRealtime API?
The launch page does not link a public API, SDK, model card, pricing page, or technical report. Developers should wait for an official platform surface rather than assume that third-party services use the same model.
What is the safest way to try SeedRealtime?
Use a short, low-risk task with an observable answer, such as watching for one page or step. Avoid private conversations and sensitive documents, record false alarms and missed events, and treat the experience as a product trial rather than a reliability test.
Discover practical AI products and emerging tools at AIToolHunt.